Skip to content

2026

GIOS Syllabus Week

The first week of GIOS is upon us! Going forward, I will be using these blog posts to document my knowledge as I progress through the class.

I take academic integrity seriously, so I will not be posting any code snippets from assignments on my blog.

Working through the modules:

  • 0.5 - 2 hours of lectures per week

  • 3 projects each with a 3 week timeline

GIOS Diagnostic Quiz

C concepts to know:

  • Structs, arrays, pointers, and reference types

    • a struct is a data structure that contains member variables

    • arrays are iterable data structures that store data in contiguous memory

    • pointers are references to variables. they are memory addresses, and they are declared by specifying the type of variable they point to followed by a *. To get the address of a variable, prepend the variable with an ampersand '&'. Use pointers to pass variables by reference. Dereferencing a null pointer is undefined behavior in C, so here are several ways to address it

      • initialize the pointer immediately

      • perform safe null checks (verify that pointer is not null before extracting its value)

      • set pointers to null after freeing memory. when a pointer's memory is cleared, it becomes a dangling pointer. anything it points to is no longer governed by stack policy.

  • reference types Google search claims that there are no "reference types" in C. So this seems like what I discussed in the description about pointers, namely how a pointer variable is declared with the object type of the object it is pointing to

  • File I/O

    • Functions are called from the library
    • file workflows typically follow this sequence: open, verify, access, close
    • use the return values of functions like fgetc or fgets to control loops instead of relying solely on feof(fp).
    • feof() is only set to true only after a read operation attempts to fetch data and fails
      // opening a file returns a file pointer which can be accessed
      // the second argument is a string that specifies the access mode.
        // "w": write - creates a new file or overwrites an existing file
        // "a": append - writes to the end of the file or creates a new file if missing
        // "r": read - reads the file, returns NULL if the file does not exist
        // "r+": read and write - reads and writes to the file, returns NULL if the file does not exist
        // "w+": write and read - creates a new file or overwrites an existing file
        // "a+": append and read - writes to the end of the file or creates a new file if missing
      FILE *fp = fopen("a_file.txt", "w");
      
      // verify that the file open was successful (did not return a NULL pointer)
      if (fp == NULL) {
        printf("Error opening file!\n");
        return 1;
      }
      
      // writing functions
      // fputc(int char, FILE *fp) - writes a character to the file. can pass in a character literal/variable or an integer for the ASCII value
      // fputs(const char *str, FILE *fp) - writes a string to the file
      // fprintf(FILE *fp, const char *format, ...) - writes formatted data to the file. first argument is output stream (can be file or console), second argument is a format string, and the rest are the values to be formatted. can use format specifiers like %d for integers, %f for floats, %s for strings, etc.
      // fwrite(const void *ptr, size_t size, size_t count, FILE *fp) - writes data from memory to file. first arg is pointer to block of memory, second is size of each element in bytes, count is the total number of elements to write to file, stream is the pointer to the file where the data will be written
      // * size_t is a specialized unsigned integer type that can represent the size of any valid object or memory block on the host system. it is the official type returned by the sizeof operator
      
      // reading functions
      // fgetc(FILE *fp) - reads a character from the file
      // fgets(char *str, int n, FILE *fp) - reads a string from the file. first arg is pointer to destination string, n is the max number of characters to read including the null terminator, fp is the pointer to the source
      // fscanf(FILE *fp, const char *format, ...) - reads formatted data. example: int items_read = fscanf(file, "%49s %d %f", name, &age, &gpa);
      // fread(void *ptr, size_t size, size_t count, FILE *fp) - reads data from file into memory. first arg is pointer to block of memory, second is size of each element in bytes, count is the total number of elements to read from file, stream is the pointer to the file from which the data will be read
      
      // file navigation
      // fseek(FILE *fp, long offset, int whence) - moves the file pointer to a specific location in the file. whence can be SEEK_SET (beginning of file), SEEK_CUR (current position), or SEEK_END (end of file)
      // ftell(FILE *fp) - returns the current position of the file pointer
      // rewind(FILE *fp) - sets the file pointer to the beginning of the file
      
      // close the file when finished to avoid dangling pointers
      fclose(fp);
      return 0;
      
  • Use of command line parameters
    • argc tracks the total number of arguments passed, including the program name itself
    • argv is an array of null-terminated strings representing the arguments passed to the program
    • argv[argc - 1] gives the last argument passed to the program
    • argv[argc] is guaranteed to be a null pointer
        int main(int argc, char *argv[]) {
          // Your code here
          return 0;
        }
      
  • Pass-by-reference and pass-by-value
    • all arguments in c are passed by value, but arguments can be passed by reference by explicitly passing pointers
    • passing by value copies entire objects into the function (high overhead)
  • Dynamic memory allocation using malloc()
    • dynamically allocate memory for objects at runtime
    • free allocated memory using free() to avoid memory leaks (write one free for every malloc)
    • use sizeof()
  • Use of C libraries
    • #include<stdio.h>
  • Debugging programs
    • compile with flags
      • # gcc -g -Wall -Wextra program.c -o program
    • run the program with gdb. gdb is an interactive debugger that is controlled via gdb commands in the gdb command line interface. use a cheat sheet for commands
      • # gdb ./program
  • Reading documentation
  • Iterative design
    • design and test small bits of code as you build up to the full functionality. can save lots of time when the program becomes more complex. also helps you understand the smaller details of the program.
  • Good coding standards
    • use void in function parameters if function takes no arguments
    • replace hard-coded numbers with const variables when possible
    • check return values
    • manage memory carefully

C Programming Examples

Linked List

  • it's a dynamic data structure whose length can be modified at runtime
  • linked lists are preferred when the volume of data to be stored cannot be determined in advance
  • a node contains the data and the pointer to the next node
  • this is how you can create a node struct test_struct *ptr = (struct test_struct*)malloc(sizeof(struct test_struct));
    • malloc returns a void pointer, which is then typecast into a struct test_struct pointer.
  • now the node can be updated like so:
    • C ptr->val = val; ptr->next = NULL;
  • The program can traverse the list by updating the current pointer to the current node's next pointer, then checking the value of that node. If there is no match, the pointer can continue to be updated. If there is a match, the loop can be broken. The stop condition of the loop is if the current pointer is null.
  • Because nodes are created using malloc, a node can be deleted using free(). The adjacent nodes should be linked first.
  • the first node is always made accessible through the use of a global head pointer.
  • ``` #include #include #include

    struct test_struct { int val; struct test_struct *next; };

    struct test_struct head = NULL; struct test_struct curr = NULL;

    struct test_struct create_list(int val) { printf("\n creating list with headnode as [%d]\n",val); struct test_struct ptr = (struct test_struct*)malloc(sizeof(struct test_struct)); if(NULL == ptr) // null checking is performed immediately after malloc { printf("\n Node creation failed \n"); return NULL; } ptr->val = val; ptr->next = NULL;

    head = curr = ptr;
    return ptr;
    

    }

    struct test_struct* add_to_list(int val, bool add_to_end) { if(NULL == head) { return (create_list(val)); }

    if(add_to_end)
        printf("\n Adding node to end of list with value [%d]\n",val);
    else
        printf("\n Adding node to beginning of list with value [%d]\n",val);
    
    struct test_struct *ptr = (struct test_struct*)malloc(sizeof(struct test_struct));
    if(NULL == ptr)
    {
        printf("\n Node creation failed \n");
        return NULL;
    }
    ptr->val = val;
    ptr->next = NULL;
    
    if(add_to_end)
    {
        curr->next = ptr;
        curr = ptr;
    }
    else
    {
        ptr->next = head;
        head = ptr;
    }
    return ptr;
    

    }

    struct test_struct search_in_list(int val, struct test_struct prev) { struct test_struct ptr = head; struct test_struct *tmp = NULL; bool found = false;

    printf("\n Searching the list for value [%d] \n",val);
    
    while(ptr != NULL)
    {
        if(ptr->val == val)
        {
            found = true;
            break;
        }
        else
        {
            tmp = ptr;
            ptr = ptr->next;
        }
    }
    
    if(true == found)
    {
        if(prev)
            *prev = tmp;
        return ptr;
    }
    else
    {
        return NULL;
    }
    

    }

    int delete_from_list(int val) { struct test_struct prev = NULL; struct test_struct del = NULL;

    printf("\n Deleting value [%d] from list\n",val);
    
    del = search_in_list(val,&prev);
    if(del == NULL)
    {
        return -1;
    }
    else
    {
        if(prev != NULL)
            prev->next = del->next;
    
        if(del == curr)
        {
            curr = prev;
        }
        else if(del == head)
        {
            head = del->next;
        }
    }
    
    free(del);
    del = NULL;
    
    return 0;
    

    }

    void print_list(void) { struct test_struct *ptr = head;

    printf("\n -------Printing list Start------- \n");
    while(ptr != NULL)
    {
        printf("\n [%d] \n",ptr->val);
        ptr = ptr->next;
    }
    printf("\n -------Printing list End------- \n");
    
    return;
    

    }

    int main(void) { int i = 0, ret = 0; struct test_struct *ptr = NULL;

    print_list();
    
    for(i = 5; i<10; i++)
        add_to_list(i,true);
    
    print_list();
    
    for(i = 4; i>0; i--)
        add_to_list(i,false);
    
    print_list();
    
    for(i = 1; i<10; i += 4)
    {
        ptr = search_in_list(i, NULL);
        if(NULL == ptr)
        {
            printf("\n Search [val = %d] failed, no such element found\n",i);
        }
        else
        {
            printf("\n Search passed [val = %d]\n",ptr->val);
        }
    
        print_list();
    
        ret = delete_from_list(i);
        if(ret != 0)
        {
            printf("\n delete [val = %d] failed, no such element found\n",i);
        }
        else
        {
            printf("\n delete [val = %d]  passed \n",i);
        }
    
        print_list();
    }
    
    return 0;
    

    } ```

    Working with Time and Dates

    • referenced from Beej
    • i like this resource better codingunit c time tutorial
    • use the #include<time.h> header
    • GMT/UTC is a universally agreed-upon time
    • used for events that happen once
    • local time is used for events that happen the same time in every time zone (i.e. noon)
    • there are two main types when it comes to time:
    • time_t, which represents the number of seconds since Epoch (Jan 1, 1970 UTC). it can also be negative to denote times before epoch.
    • struct tm, which holds the components of calendar time
    • some common time operations in c: C time_t now; // Variable to hold the time now now = time(NULL); // You can get it like this... time(&now); // ...or this. Same as the previous line. printf("Current time: %s", ctime(&now)); // ctime converts time_t into a human-readable string // convert a struct tm into time_t using the mktime command struct tm str_time; time_t time_of_day; str_time.tm_year = 2012-1900; str_time.tm_mon = 6; str_time.tm_mday = 5; str_time.tm_hour = 10; str_time.tm_min = 3; str_time.tm_sec = 5; str_time.tm_isdst = 0; time_of_day = mktime(&str_time); printf(ctime(&time_of_day)); // note that if the tm_hour and the output of ctime differ by one hour, daylight savings time is in effect. this could depend on the date of the year and/or the tm_isdst flag. // using difftime to measure runtime of code block time_t start,end; volatile long unsigned counter; start = time(NULL); for(counter = 0; counter < 500000000; counter++) ; /* Do nothing, just loop */ end = time(NULL); printf("The loop used %f seconds.\n", difftime(end, start)); return 0; // converting time_t to utc and using timezones time_t raw_time; struct tm *ptr_ts; time ( &raw_time ); ptr_ts = gmtime ( &raw_time ); // converts to greenwich mean time printf ("Time Los Angeles: %2d:%02d\n", ptr_ts->tm_hour+PST, ptr_ts->tm_min); printf ("Time Amsterdam: %2d:%02d\n", ptr_ts->tm_hour+CET, ptr_ts->tm_min); return 0;
    • conversions between the two types can be done (see guide for details)

    Psuedo-Random Numbers

    • rand() returns a random number between 0 and RAND_MAX (guaranteed to be at least 32767) - depends on implementation of c library C int rand(void) // accepts no arguments

    String Functions

    • Source C strlen() Get length of a string. strcpy() Copy one string to another. strcat() Link together (concatenate) two strings. strcmp() Compare two strings. strchr() Find character in string. strstr() Find string in string. strlwr() Convert string to lowercase. strupr() Convert string to uppercase.

C++ Programming

C++ strings

C++ OOP

C++ class

Pointers in C++

  • Reference
    • C++ pointers are just like C pointers!
    • Smart pointer is a pointer that is wrapped in a class that takes care of
      • lifetime of dynamically allocated memory

Lock guard

  • Reference
    • a scoped mutex wrapper that provides a safe, exception proof way to lock and unlock a mutex using Resource Acquisition is Initialization (RAII)
    • a mutex is a synchronization primitive used in multi-threaded programming to prevent concurrent access to shared resources

Command Line Concepts

  • Read man pages (man)
  • Navigate directories (cd, ls, pwd)
  • Move and copy files (mv, cp)
  • Adjust permissions or groups (chown, chmod)
  • Run executables (gcc, C executables, or other tools)

Makefile concepts

  • Colby Make tutorial (for usage examples)
  • The Make File tutorial (intuitive explanations)
  • projects must be submitted with makefiles to automate the build process of their c programs
  • the goal of makefiles is to compile whatever files need to be compiled, based on what files have changed
    • i've always used a single command on the CLI to compile my code, so i am also trying to figure out what makefiles do better
  • the c makefile uses a combination of rules and macros (variables) to compile. rules specify targets, dependencies, and the commands needed to create them. commands should alwayas be indented with tabs.
  • things to know:
    • Targets and dependencies
      • the list of dependencies following a target declaration tells make to check if those files have changed since the last compilation. if they have, then make will recompile the target. if those files have not changed, make will not recompile the target (if the target file already exists), even if the target is explicitly called out in the make command
    • Comments (always useful!)
      • each comment line starts with #
    • Variables (compiler, flags, etc.) - AKA macros are defined at the top of the makefile
    • Calling make from the command line
      • calling make with no arguments executes the first rule in the file
        # specify the compiler
        CC=gcc
        
        # specify options for the compiler
        CFLAGS=-c -Wall
        
        all: hello
        
        hello: main.o hello.o
            $(CC) main.o hello.o -o hello
        
        main.o: main.cpp
            $(CC) $(CFLAGS) main.cpp
        
        hello.o: hello.cpp
            $(CC) $(CFLAGS) hello.cpp
        
        clean:
            rm -rf *o hello
        

Learning goals!

The course will answer three questions: - What are operating systems? - Why are they needed? - How are they designed and implemented to provide the required functionality?

To provide its intended functionality, an operating system uses abstractions, mechanisms, and policies for - processes and process management - threads and concurrency, and in general challenges related to multithreading - managing hardware (CPU, memory) resources via scheduling and memory management - OS services such as communication and I/O - OS support for distributed services including remote procedure calls (RPC), distributed filesystems, and distributed memory - introduce systems software that is used in data center and cloud environments

Practical projects are intended to supplement the theory and impart an appreciation for operating systems. projects will provide challenges related to - threads, concurrency, and synchronization - multiprocesses on a single node (like a server machine): inter-process synchronization, scheduling... - multi-node mechanisms: remote procedure calls, ... - measuring and evaluating design decisions with respect to performance

To carry out these ends, the programming projects are to be written in C on a Linux operating system. standard linux libraries will be used, such as pthreads.

There is no required textbook, but Ada recommends the "dinosaur" books: - Operating Systems Concepts, - Operating Systems Concepts Essentials. She also recommends the Tannenbaum Modern Operating Systems textbook and the Operating Systems: Three Easy Pieces

Seminal research papers will be provided, as well as tutorials and technology surveys.

Online resources will be provided for C programming, PThreads, and other libraries.

A toy shop metaphor will be used when describing the operating system.

REMIMDER: READ PIAZZA POSTS

P1L2 Playlist: OS Components, Abstractions, Arbitrations, and System Calls

Dipping the toe in the water!

What is an operating system and what role does it play in computers?

  • it's a piece of software that abstracts (simplifies conceptually) and arbitrates (manages) the underlying hardware
  • it offers many abstractions and arbitrations for the various underlying hardware systems
  • how does it manage and arbitrate the underlying hardware?
    • it directs operational resources, which include CPU, memory, and peripheral devices
    • it enforces working policies, such as fair resource access, limits to resource usage with respect to processes
    • manages the difficult of complex tasks by abstracting hardware details. system calls are such an abstraction
  • what are the underlying hardware pieces of a computer system? all of these will be used by multiple applications, except in some specific environments like embedded platforms or sensors
    • processor (1 or more). today's CPUs have multiple cores (processing element)
    • main memory
    • network interconnects, such as ethernet port or wifi card
    • graphics processing cards (GPU)
    • storage devices such as HDD, SSD, flash USB drives
  • what kind of applications use these resources?
    • on a client computer, this could be a browser, text editor, video conferencing apps
    • on a data center server, this could be a database server, web server, a file storage system, a computationally intensive simulation, etc.
    • an os is the software that sits between the hardware and the application software
  • what kind of hardware complexity does the operating system hide?
    • an example would be disk sectors or blocks when saving output of a computation in you program
      • it manages a higher level abstraction called a file, which has read and write functions
    • another example would be the bits and packets that are sent after receiving a request from a client
      • Os abstracts this into a send/receive socket
  • how does the OS manage the underlying hardware?
    • decides which and how many of the hardware resources to use
    • for example, it decides how much memory to use for an application, and schedules application tasks on the CPU
    • it also decides when the various applications get to access the hardware
    • also provides isolation and protection, meaning that the various applications that are using the same hardware resources don't interfere with each other. for example, the os would allocate certain addresses in memory to specific applications
    • managing hardware is also important on devices that were once considered embedded devices, such as our phones.
  • the os hides hardware details from the application, and has policies that govern how applications may interact with the underlying hardware
  • is it part of the operating system or not?
    • part of os:
      • device driver
      • file system
      • scheduler
    • not part of os:
      • file editor (application)
      • cache memory (hardware)
      • web browser (application)
  • is it an abstraction or arbitration?
    • arbitration
      • distributing memory between multiple processes
    • abstraction
      • supporting different types of speakers (applications don't need to worry about speaker details)
      • interchangeable access of hard disk or ssd (application doesn't need to worry about storage details)

What are some examples of operating systems?

  • operating systems differ by the kind of environment they target. for example, some os's are for pc desktops, some are for servers, some are for embedded devices
  • some common desktop operating systems are microsoft windows, unix-based (mac osx, linux)
  • Ada considers embedded operating systems to include: ios, android, and symbian

What are the key components of the operating system?

  • an operating system supports a number of higher level abstractions and mechanisms that operate on top of these abstractions
  • abstractions
    • correspond to applications
      • process
      • thread
    • corresponds to the hardware
      • file
      • socket
      • memory page
  • mechanisms
    • for applications
      • create (or launch an application)
      • schedule (to run it on the CPU)
    • for hardware
      • open
      • write
      • allocate
  • policies govern how mechanisms will be used to manage the underlying hardware
    • a policy controls the max number of sockets that a process can have access to
    • control which data can be removed from memory based on some algorithm like least-recently used (LRU), earliest deadline first (EDF)

Memory management example:

  • abstraction:
    • memory page - corresponds to some addressable region of memory with fixed size
  • mechanisms to operate on that page:
    • allocates that page in dram, maps that page into the address space of the process (allows process to access the physical memory that corresponds to the contents of that page)
    • page can be moved to different locations in physical memory
    • page can be stored on disk if we need to make room for other content in physical memory
  • policies:
    • it's faster to access items in memory, so there must be some policy governing when items get moved from memory to disk
    • least recently used -LRU is such a policy
      • rationale is that pages that have not been used in a while are likely to not be used imminently
    • the act of moving items between disk and memory is known as "swapping"

What are some design and implementation considerations of operating systems?

  • separation of mechanism and policy
    • this makes mechanisms flexible, meaning they can be used in different types of policies
    • memory management policies: LRU, LFU (least frequently used), random
      • for these policies, we might want to have a mechanism that tracks the frequency or the time of memory access
    • knowing this, policies must be defined for a "common case". some considerations:
      • where will the os be used?
      • what machine will it be run on? what resources are available on that machine?
      • what will the user want to execute on that machine?
      • what are the workload requirements?
    • with answers to these questions, and an awareness of what mechanisms are available, a policy can be defined

How does the OS manage access to the hardware?

  • it uses a user/kernel protection boundary
  • "unprivileged mode" is designated for user-level applications. this is one side of the boundary. aka user mode
  • "privileged mode" is reserved for kernel-level operating system actions. aka kernel mode
  • traps, system calls, and signals
  • user-kernel switch is supported by hardware, meaning there is a bit in the CPU that reflects whether an operation has access to the hardware.
    • if an operation only has user-level privileges but tries to perform a privileged operation on the hardware, it will cause a trap
      • when a trap occurs:
        • application is interrupted
        • cpu hands control over to the os
        • operating system determines what caused the trap
        • os verifies if it should grant the access or terminate the process if the attempt was illegal. this depends on the policies that are supported by the os
  • applications can interact with the hardware through system calls
    • the operating system exposes a system call interface that the applicatoin can explicitly invoke if they want the os to perform a service/privileged access on their behalf. examples include
      • open (a file)
      • send (via a socket)
      • mmap (allocate memory)
  • the operating system can feed "signals" back to applications, which is a mechanism for the os to pass notifs into the applications

Flow of a synchronous system call

  • user process executes
  • user process passes its arguments to the system call and makes the system call
  • process switches context to kernel/privileged mode, where the system call is executed
    • context switch involves switching to kernel memory where the system call instructions can be executed
  • upon completion, system call outputs are returned to the user process address space

synchronous system calls are considered expensive operations because

  • an application must write arguments
  • save all relevant data at a well-defined location before handing off to kernel process
    • this location must be well defined so the os kernel, based on the system call number, can determine the number and location of the arguments
    • arguments can be passed directly between user process and system kernel, or they can be passed indirectly by reference
  • make a system call using the specific system call number
  • the process waits until the system call completes

the operating system traps application instructions or memory access requiring special privilege. for instance, the application cannot change the contents of certain registers or give itself more cpu or memory. only the os can do that.

Tradeoffs of system calls:

  • It can take 50-100 ns on a 2Ghz machine running linux to finish the steps involved in a system call - real overhead for the system!
  • system call transitions affect the hardware cache usage
    • application performance depends highly on ability to use the hardware cache. accessing the cache requires an order of a few cycles. accessing memory is on the order of a few hundred cycles.
    • when operating system is executing a system call, it will likely bring its contents into the cache, replacing some of the application content that was in the hardware cache. the application would need to access its content from memory, which, as stated before, is on the order of hundreds of times more expensive to access

Examples of system calls: - - - -

Types of operating system design - Monolithic - everything the operating system could need is included in the box - this leads to less maintainability issues, but is more cumbersome (larger operating system size) - Modular - the operating system contains a few basic services - only download the services you need - some performance tradeoffs because different services need to be designed with the operating system's interfaces in mind - modularity comes at the cost of some overhead - maintainability concerns (service updates can introduce bugs or service versions can be deprecated) - commonly used in practice - Microkernel - at the os level, the microkernel can support some basic services such as address spaces and threads (context) for apps - databases, and even file systems and device drivers (commonly included in os), operate at the user/unprivileged level - by virtue of this design, these services require a lot of inter process communication (IPC), which the microkernel does support - upsides of microkernel are the small, lightweight system size, leading to lower overhead and better performance, and the verifiability/testability of code to behave as it should - downside is that it is not very portable because it is customized to the hardware. also introduces complexity because there are different variations of the microkernel for different platforms, meaning some services will need to be custom-written. because more services are in the user/unprivileged layer, they require more interaction with the kernel for inter process communication, which as stated before, is costly

Linux architecture - there are several "layers" to the linux architecture. from lowest to highest - hardware - kernel - linux operating system - user mode - standard library - standard utility programs - user interface (application)

The kernel itself has several subcomponents, which all have well defined functionality and interfaces. they can be independently modified or replaced, which is what enables modularity - i/o component - manages the virtual file system, which encompasses - terminals - character device drivers

- memory management component
    - virtual memory
    - paging page replacement
    - page cache
- process management component
    - signal handling
    - process/thread creation and termination
    - CPU scheduling

Mac architecture

Setting up a development environment and testing it

Source - this github repo contains a guide explaining several configuration options, their respective starter packages, and articles about using the gdb debugger, remote gdb debugging

Two test frameworks are suggested: munit and cmocka. A quick google search summary described munit as a lightweight unit test framework, and cmocka as a mature, feature rich framework that can also detect memory leaks, buffer overruns, and underruns during test execution. it can also catch and recover from segfaults or illegal instructions mid-test. Cmocka's feature set might take more time to learn up front, but may end up saving more time in the long run. So I chose to download and learn cmocka. It turns out, the API documentation is quite good and there exists some quick startup guides online, so I feel pretty confident about using it.

I compiled a simple cmocka test harness to test my environment.

An Introduction to Programming with Threads

Source

  • A thread is a sequential flow of control
  • having multiple threads in a program means the program, at any given moment, has multiple instances of execution, one in each of its threads
  • programmer must decide when to use multiple threads, and also be aware that the computer may not always execute the threads simultaneously
  • having threads execute in the same address space means the threads can access the same section of memory
  • thread facilities are advertised to be "lightweight". thread creation, destruction, existence, and synchronization primitives are cheap enough that the programmer can use threads for concurrency needs
  • What's the point of concurrency?

    1) modern processors have multi cores. concurrency allows us to take advantage of the available hardware

    • the alternative to concurrency is to have the multiple processes to eadch occupy a separate address space of their own, which is costly: it is expensive to set up, and the cost of communicating between different address spaces is high
    • concurrency allows processors to be used cheaply

    2) threads can be assigned to slow devices such as disks, networks, terminals, and printers. when the thread is waiting for input, the computer should be able to do other useful work, so the input and processes are separated in different threads.

    3) Multitasking is also achievable with multiple threads. Each time a user clicks on an application to start different processes, a thread can be used to handle each process. The implementation of this type of application probably also depends on a separate thread to accept mouse click input.

    4) Threads can also be used on distributed systems to handle incoming requests. Threads can be used to handle each client's request in parallel instead of serializing them, such as in the case of a file server or spooling print server.

    5) Threads can also be used in applications to reduce the latency of operations (time between initiating a procedure and getting the outputs of that procedure). The book gives the example of adding/removing an item from a balanced tree. The operation can be returned to the caller while the tree is rebalanced in a separate thread. This is an example of using concurrency to defer the work of a procedure since the outcome does not depend on it. The benefit of reducing latency to the end user is a more responsive program.

Designing a Thread Facility

A facility is a construct containing multiple threads accessing some shared resource. Only one thread is allowed to access the resource at a time. This is called asynchronous execution.

  • Thread creation

    • A fork is a function that creates a thread by defining the thread's procedure and giving the thread arguments (the necessary ingredients to execute that procedure). it can be thought of as a thread handler
    • The thread "dies" when it returns the results of its procedure
    • a fork returns to its caller a handle/reference to the newly created thread
    • the thread handle can be passed to a join procedure, which waits for the thread to terminate and returns the result of the given thread's initial procedure. join is a synchronization arrangement
    • join is not always used and not always necessary, because threads can communiate their results by some synchronization arrangement other than join
  • mutual exclusion (MUTEX)

    • when a thread has access to a shared resource, it locks the resource so no other threads can use it. a MUTEX is a primitive that specifies a particular snippet of code, such as global variables, that only one thread can execute at any time
    • has two states: locked and unlocked
    • a thread executing inside the mutex has a "lock", or is said to "hold the mutex", meaning no other threads can access the mutex. any thread that attempts to access a locked mutex is said to "block" (added to the mutex queue) until the mutex is unlocked
    • a concrete example of a mutex in action is using it to allow only one thread to update a linked list at a time. a mutex and linked list head are declared. then, inside a 'lock' clause, the commands to add a new element to the linked list are executed. this prevents multiple threads from updating the linked list at a time.
    • a mutex can also be used to protect part of a data structure. to express this, the lock clause would begin by selecting the mutex field of the data structure
    • a mutex can be understood as a resource scheduling mechanism. the resource is the shared memory inside the lock clause, and the scheduling policy is one thread at a time
  • condition variables - waiting for events

    • a thread has a mutex lock until the lock clause is finished executing, but for more complicated scheduling policies, a condition variable is used
    • a condition is always associated with a mutex and the data protected by that mutex
    • a monitor consists of some data, a mutex, and zero or more condition variables
    • a condition variable has three types of operations: wait, signal, and broadcast, which are triggered by conditions
      • when wait is triggered, the thread is blocked (queued) and the mutex is unlocked.
      • the signal operation does nothing unless a thread is blocked on the condition variable, in which it unlocks one or more blocked threads
      • broadcast awakens all the threads currently blocked on the condition variable
    • when a thread is awoken inside 'wait', it relocks the mutex and returns. unless the mutex is already locked, which will keep the thread blocked on the mutex until it is available
    • if the shared resource is not available, the thread unlocks the mutex and blocks by calling wait
    • a thread can call a signal when it is done with its task
  • alerts - escaping a thread from a long-term waiting event

    • threads have states
    • one state of a thread is stored in the alert-pending state, which is initially false
    • if AlertWait is triggered, a threads alert-pending is changed from true to false, relocks the mutex, and raises the exception 'alerted'
    • if alertwait is triggered, a thread that was blocked on a condition can be awoken, lock the mutex, and raise the 'alerted' exception
    • calling alert on a thread that is not blocked simply sets its alert-pending boolean to true
    • a testalert call atomically tests and clears the thread's alert-pending boolean
    • example of using an alert: a thread is waiting but a second thread has determined that the first thread no longer needs to wait, the second thread will call Alert(firstThread)

Using a Mutex: Accessing Shared Data

  • unprotected data
    • unsynchronized behavior, or mutating unprotected data with multiple threads, can result in nondeterministic behavior. behavior depends on the precise timing relationship between threads. page faults, the use of real time timer facilities, or asynchrony in a multi-processor system are causes of this nondeterministic behavior. so data must be protected with mutexes
    • "make your mutexes as simple as possible, but no simpler"
  • invariants
    • a boolean that is true when the mutexed data is unlocked
    • it's used to describe what the mutex is protecting, when the data protected by the mutex is complicated
    • it's an informalism that helps programmers describe what the mutex is protecting
    • it describes a state about the mutexed data - for example, if a thread updates a mutexed null array at index i, the invariant is that "i is the index of the first null in the array and all elements in the array after i are null". the invariant is false when/after the thread operates on the array, but true before the mutex is locked by a thread
    • threads are responsible for restoring this boolean when finished with the operation, before calling 'wait'
  • cheating
    • the idea that you must use a mutex to protect every global variable is based on the model where the actions of the threads are arbitrarily interleaved. there are some instances where this model doesn't hold true, but the conditions are not easily generalized
    • this applies to simple variables as well
    • one "cheat" is to use unsynchronized access as a "hint", knowing that the mutexed operation you really want to call is expensive
      • this cheat only works if the programming language you are using guarantees several assumptions:
        • reaading it without a mutex will not cause a runtime error
        • reading it when its value is False will give you the value False (for example)
  • deadlocks involving only mutexes
    • Thread 1 locks mutex A, thread 2 locks mutex B, Thread 1 is blocked on mutex B, thread 2 is blocked on mutex A. so they don't go anywhere because they are stuck in the queue!
    • to solve this, arrange for any thread that has to lock two mutexes to lock them in a specific order every time. for example, this would mean that a thread that needs to lock mutex A and B must lock them in that order
    • a technique that makes this partial order more achievable requires a certain condition. that condition is that the two threads are not modifying the exact same data (for example, thread 1 needs to access the first three elements of an array and thread 2 only needs to access the next three elements). it then becomes possible to place partial locks on the array rather than a lock on the entire array. in the end, requiring that threads lock in a specific order still applies, it's just being applied on a more granular level
      • the tradeoff to this technique is that the locking is more complicated and you are likelier to have unsynchronzied access to shared data. but it is faster if executed correctly
    • having a program deadlock is preferable to having it provide the wrong answer
  • poor performance through lock conflicts
  • releasing the mutex within a lock clause
Using a Condition Variable: Scheduling Shared Resources

Using Fork: Working in Parallel

Using Alert: Diverting the Flow of Control

Additional Techniques

Building Your Program

Concluding Remarks

Advanced Learning Algorithms

Foreword

After completing the Supervised Machine Learning course as part of the Machine Learning Specialization taught by Andrew Ng on Coursera, I am now working on the Advanced Learning Algorithms course, which covers neural networks, training, and decision trees, as well as how to build a practical machine learning system. I coded a decision tree as part of an assignment and read about neural networks in ML4T, so I am excited to learn from Andrew Ng's perspective and get some hands-on experience with neural networks.

Neural Network History

The original motivation for neural networks (NN) was to mimic, with software, how the human/biological brain learns and thinks. Today, NN, also known as artificial neural networks (ANN), have become very different from how we think the brain works and learns. Some of the biological motivations still remain in the way we think about ANN or computed NN today.

NN was first invented in the 50's. NN were then used in the 80's an early 90's to recognize handwritten postal codes for mail routing and dollar figures in handwritten checks. The fell out of favor, and experienced a resurgence in popularity in the mid 2000's. It was also rebranded into "deep learning". Since then, neural networks have revolutionized many application areas. The first area that deep learning had a significant impact on was speech recognition systems (Li Deng and Geoff Hinton). Next, the technology made inroads to computer vision, with ImageNet being a milestone enabler for future research in the domain. The next "era" of deep learning became text processing or natural language processing (NLP). Nowadays, NN are used in climate change, medical imaging, online advertising, product recommendations, and many application areas of machine learning.

Neural networks were initially constructed to mimic the present understanding of the human brain. Thoughts travel through the neurons in the brain as electrical signals. A neuron gathers electrical signals through its dendrites, then sends its output to another neuron via its axon. It is this simplified model of the neuron that the neural network was based on, but they differ in that multiple neurons are simulated at once, accept the inputs, and collectively output a number. Ng caveats that biological understanding of the brain is limited, and neuroscientists continue to discover new things about the brain. The deep neural networks nowadays have been built up from engineering best practices, and any semblance of these to biological models of the brain is speculative. So mimicking current brain models is said to be unlikely to yield raw intelligence.

Neural Networks Today

Why have deep neural networks exploded in popularity? As datasets were getting larger and larger, it was getting difficult to scale the performance of traditional learning algorithms like logistic and linear regression. Researchers realized that as neural network sizes scaled up, performance increased. For "big data" applications, larger neural networks enabled performance on use cases such as speech recognition, image recognition, natural language parsing, etc. Computing deep neural networks is also why processing, or "compute", specifically GPU processing is in such high demand.

From Logistic Regressions to a Neurons

Suppose we are trying to predict a category based on numerical data. In logistic regression, the input would be the numerical data and the output would be the category. In a neural network, the output is called an activation, which is a term that comes from neuroscience. The activation would ouput a probability of the input belonging to a category, just like a logistic regression does.

Talkin' 'bout Architecture (of a Neural Network)

On the opposite ends of the network are the input layer and the output layer. The input layer is the multifeatured data. The output layer is the prediction. In the classification case, it is the probability of the input layer being of a certain category. In between the input and outer layer are "hidden" layers, which each contain multiple neurons. A "hidden" layer is called such because the data in the neurons is hidden, unlike the data in the training set. In a layer, each neuron depends on some combination of the activations from the previous layer. The first layer depends on the input layer. The output layer depends on some combination of activations from the previous layer and outputs a probability. The neural network learns which activations from the previous layer contribute most to each neuron in the next layer. One conception of these hidden layers is that they are the features that the model has created from the previous layer. A neural network model with many hidden layers has essentially "engineered" or "learned" features of features. This is useful because engineered features can predict better than their constituent features can. It also eases the burden of creating/selecting features from the practitioner.

The activations emitting from a layer can be understood as a vector of activations.

When building a neural network, a decision is made on how many layers the neural network will have as well as how many neurons each layer will contain. These decisions will affect the performance of the model. Tradeoffs will be discussed later in the course.

A multilayer perceptron is another way of describing a multilayer neural network.

How do neural networks identify a person in a photo?

Given a black-and-white portrait photo of a person, the photo can be understood as an mxn grid representation of pixel values, each taking on a value between 0 and 255. This is the data that will be the neural network's input layer. To reshape the grid into an acceptable format, we vectorize the matrix. Vectorization in this context is an operation that takes the matrix of data and stitches it together columnwise, resulting in a 1-dimensional vector of values that can be fed into a multilayer perceptron.

As stated before, each layer contains a new set of features that are constructed from those in the previous layer, and it is difficult to know the meaning of each layer's neurons - recall that the practitioner has decided on the number of neurons a layer will have and that the algorithm is learning the best activation to assign to each neuron. To build an intuitive understanding of a neural network, we can create a mental model by imagining what kinds of features each layer is "extracting" from the photo in this case.

Imaginging that the neural network in this case consists of three hidden layers, the first layer's purpose can be understood as edge detection, where each neuron is detecting the number tiny lines with orientations ranging from \(0^\circ\) to \(360^\circ\). The original photo might contain thousands of these. The next layer might "learn" to group together these tiny lines to form facial features, such as a nose, ears, eyes, mouth. The final hidden layer might learn to construct faces of different shapes and sizes from these facial features. Based on the faces constructed, the output layer assigns a probability that the picture is of a particular person. As the data is processed in each layer, each layer outputs activations of a higher level feature. The neural network is learning higher level features from the activations of the previous layer - all the practitioner has done is select the number of layers and the number of neurons in each layer.

Constructing a layer of neurons, terminology

What's actually happening in each neuron? In a classification neural network, each neuron is a linear combination of the previous layer's activations and the weights \(\vec{w}\) and \(b\) particular to that neuron. The number of weights in a neuron depends on the number of activations from the previous layer. The polynomial combination of the weights is called the pre-activation. The pre-activation is calculated by adding the bias term to the dot product of the neuron's weights and the previous layer's activations \(\vec{a}\). The pre-activation is fed into the sigmoid function to produce the neuron's activation. The activation is the input for the next layer.

Other conventions include the input layer being called layer 0, and all successive layers indexed by their respective position relative to the input layer (layer 1, 2, 3...). The output layer is the final layer. All layers that are not layer 0 or the output layer are called "hidden" layers. The function in a neuron that outputs the activation is called the activation function. In classification, the activation function is the sigmoid function.

An element of an activation \(\vec{a}\) is also known as a unit. When identifying the activation unit or its constituents \(\vec{w}\) and \(b\), a superscript denotes the layer that it's in. The subscript denotes the neuron that it belongs to. The input layer can also be denoted as \(\vec{a}^{[0]}\).

Forward Propagation

Activations of lower-index layers are being fed-forward to higher-index layers, hence the term forward propagation. It is typical to reduce the number of units per layer when progressing through the forward-prop neural network.

Tensorflow and Keras

Tensorflow is a machine learning tool package that was released by Google. In 2019, Google integrated Keras into Tensorflow and released Tensorflow 2.0. Keras is a framework developed independently by François Chollet that creates a simple, layer-centric interface to Tensorflow.

import numpy as np
import matplotlib.pyplot as plt
import tensorflow as tf
from tensorflow.keras.layers import Dense, Input
from tensorflow.keras import Sequential
from tensorflow.keras.losses import MeanSquaredError, BinaryCrossentropy
from tensorflow.keras.activations import sigmoid
from lab_utils_common import dlc
from lab_neurons_utils import plt_prob_1d, sigmoidnp, plt_linear, plt_logistic
plt.style.use('./deeplearning.mplstyle')
import logging
logging.getLogger("tensorflow").setLevel(logging.ERROR)
tf.autograph.set_verbosity(0)

# training data
X_train = np.array([[1.0], [2.0]], dtype=np.float32)           #(size in 1000 square feet)
Y_train = np.array([[300.0], [500.0]], dtype=np.float32)       #(price in 1000s of dollars)

# this is how to implement a simple linear regression in Keras
linear_layer = tf.keras.layers.Dense(units=1, activation = 'linear', )

# display weights
linear_layer.get_weights() # []
# there are no weights because the model has not been instantiated

# inputs to the linear layer must be 1d vector column, hence the reshape
a1 = linear_layer(X_train[0].reshape(1,1)) # training on just the first example
print(a1) # result is a tensor (array) with shape 1,1 (one entry)

w, b= linear_layer.get_weights() # a single weight and bias are returned because this is a linear model
print(f"w = {w}, b={b}") # these are random values. recall that you can fit an infinite number of lines to a point

# we can set our own weights
set_w = np.array([[200]])
set_b = np.array([100])

# set_weights takes a list of numpy arrays
linear_layer.set_weights([set_w, set_b])
print(linear_layer.get_weights())

# comparing tensorflow output with simple dot product - they should be the same
a1 = linear_layer(X_train[0].reshape(1,1))
print(a1)
alin = np.dot(set_w,X_train[0].reshape(1,1)) + set_b
print(alin)

# now we compare the predictions when the models are trained on all the data
prediction_tf = linear_layer(X_train)
prediction_np = np.dot( X_train, set_w) + set_b

# predictions are identical
plt_linear(X_train, Y_train, prediction_tf, prediction_np)

# below, the code is creating a tensorflow model that contains a logistic layer. tensorflow is often used to create multi-layer models. the Sequential model is a convenient means of constructing these models
# a logistic neuron can be created like so:
model = Sequential(
    [
        tf.keras.layers.Dense(1, input_dim=1,  activation = 'sigmoid', name='L1')
    ]
)

# shows the layers and number of parameters in the model. There is only one layer in this model and that layer has only one unit. The unit has two parameters, w and b
model.summary()

# we can display information about a layer like so:
logistic_layer = model.get_layer('L1') # references the layer we named 'L1'
w,b = logistic_layer.get_weights() # the weights are random
print(w,b)
print(w.shape,b.shape)

# set the weights to known values and validate
set_w = np.array([[2]])
set_b = np.array([-4.5])
# set_weights takes a list of numpy arrays
logistic_layer.set_weights([set_w, set_b])
print(logistic_layer.get_weights())

# get predictions (tensorflow's prediction matches that of the sigmoid function)
a1 = model.predict(X_train[0].reshape(1,1))
print(a1)
alog = sigmoidnp(np.dot(set_w,X_train[0].reshape(1,1)) + set_b)
print(alog)

8/24 update: I'm taking GIOS this semester, and class materials were just released! So this is a reminder to future me to come back to this: https://www.coursera.org/learn/advanced-learning-algorithms/lecture/rJMKC/inference-in-code

How I discovered cycling

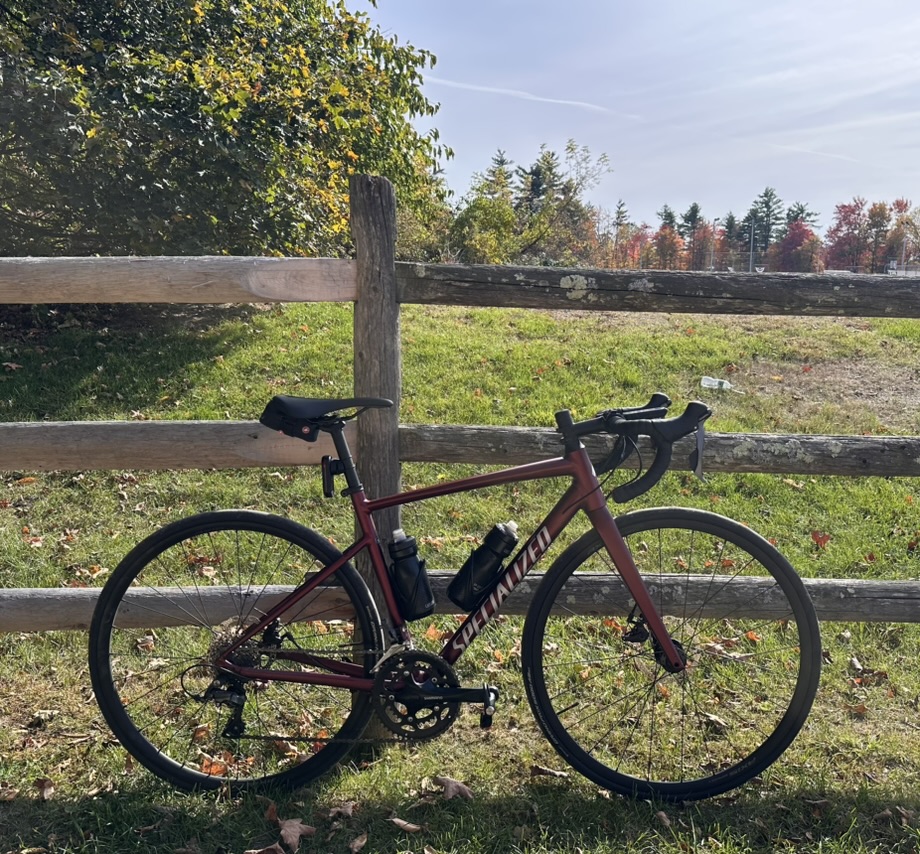
Cycling photo

In December of 2025, I suffered a shin splint that would, unbeknownst to me, sideline me from running for several weeks. I had just run 17:08, my personal best in the 5k, and allowed myself rest one day before running a difficult tempo Tuesday workout with the Cambridge Running Club.

The culprit was overuse - and luckily, a visit to the orthopedic specialist ruled out any fractures. I breathed a sigh of relief. The next day, I purchased an indoor trainer for my Specialized Allez. I had bought the road bike more than two summers ago, when I suffered my first injury as a budding-but-serious runner: patellofemoral pain syndrome. The Allez was an entry-level bike, but I knew my cycling foray would be short-lived. Ruby, as I had named her, and I traveled to several nearby towns that, until then, I had little reason to visit. We rolled over roads and enjoyed the verdant tranquility of the well-to-do Boston suburbs. Gradually, my knee pain subsided, and I found myself spending less time on the saddle and back to haunting Beacon St, Longfellow Bridge, the Esplanade, and Massachusetts Avenue in my stacked running shoes. My chapter with Ruby had come to a close, but I was glad that she and I had shared some enjoyable memories together. I was comforted by the knowledge that she and I would pick up where we left off, were I to return.

Supervised Machine Learning Basics

After taking Machine Learning for Trading (ML4T) this spring, where I built a trading bot using machine learning principles, I was curious about applying the algorithms to areas outside of finance. In the course, I built a few machine learning algorithms from scratch in Python. It would pretty tedious to build the algorithms from scratch or tweak them to every use case ain't nobody got time for that, however, and I wanted to focus more on their applications in new domains. Andrew Ng's Supervised Machine Learning course seemed like a great way to dip my toe in the water and use some modern-day frameworks, so I started the course.

Within the first few minutes of the course, I was presented with a few examples of supervised learning in practice: spam filtering, speech recognition, machine translation, online advertising, self-driving cars, and defect detection in manufacturing. Online advertising was the most illustrative example: features would be the ad and user info, and the output would be whether the user clicks on the ad. In the case of

Unsupervised learning received some coverage as well. An example of an unsupervised learning algorithm is in Google's news aggregation tile, where similar stories from different news outlets are clustered together. This is an example of a clustering algorithm. A clustering algorithm finds structure in data without being explicitly told what that structure should look like groups similar data together. So in the case of the google tile, it finds similar news articles based on several keywords that they share - these keywords are discovered by the algorithm itself!

More generally, an unsupervised learning algorithm receives data with labeled inputs and unlabeled outputs. Clustering is one example. Anomaly detection is another. An example of anomaly detection is detecting fraud in the financial systems, such as unusual transactions. Another example of unsupervised learning is dimensionality compression, where the resulting dataset is much smaller.

Cost function

I was curious why mean squared error was used in ML4T. This course addresses a few reasons why MSE is a useful cost function: - taking the mean of the errors prevents the cost function from unboundedly increasing as the training set increases in size - the shape of a squared function is convex. in other words, the cost function will always have a minimum which gradient descent can exploit in all dimensions

Additionally, this course uses a MSE cost function with a coefficient of 1/2. More on why in the gradient descent section.

Gradient descent

\(\omega = \omega - \alpha \frac{\partial J(\omega)}{\partial \omega}\)

  • With respect to model weights, simultaneous updates occur when weights are updated in succession. Ng cautions against using non simultaneous updates in gradient descent because this is not how gradient descent is typically implemented, which means the non simultaenous update may have different characteristics. instead, all weights should be updated before the next iteration

gradient descent is described as an interative update to a parameter. the updated parameter gets the result of the product of (a learning rate factor and [partial] derivative) subtracted from the previous parameter value.

In the ML community, a "batch" gradient descent algorithm is one that is used to tune the model on the "batch" - that is, the whole - of training data.

Notably, there exists an alternative to gradient descent, called the normal equation, that works only for linear regression. It can solve for the weights without iterations. It's practical when the number of features is small and may be used in some machine learning libraries for linear regression applications.

Derivation

The reason for the 1/2 coefficient becomes apparent when deriving the gradient from the MSE cost function. Using the chain rule from calculus, the quadratic is differentiated into a linear function with a coefficient of 2. This is what the 1/2 coefficient from before addresses.

Learning rate

If the learning rate \(\alpha\) is too small, gradient descent makes tiny updates and takes a long time to reach the minimum. If \(\alpha\) is too large, the updates can overshoot the minimum, bounce around, or even fail to converge.

The main idea is that \(\alpha\) controls the step size of each gradient-descent update. The best learning rate is large enough to make progress efficiently, but small enough that the cost keeps moving downward instead of oscillating or diverging. In practice, a dynamically-adjusted alpha could yield better results. For example, alpha can be relatively large at the outset, but iteratively diminished the closer the GD function gets to the local minima.

Ng notes that even with a fixed learning rate, it is still possible for GD to converge on the local minimum. Imagining a simple quadratic curve: as the iterative updates to the parameter approach the minimum, the magnitude of the gradient decreases such that the magnitude of the parameter's updates reduce over time.

The most important takeaway of this section is that by periodically checking the cost function during a gradient descent, you can see whether or not the algorithm is converging or diverging. If it is diverging, this may be a signal to decrease the learning rate.

Convex function

The quadratic mean squared error (MSE) function is a convex function. The GD algorithm will always converge to its global minimum. This is in contrast to functions that have multiple local minima. The GD algorithm is not guaranteed to converge to the global minimum because it ultimately depends on where the initial guess of the parameters is.

Multiple multivariate regression

Several features, one output. a set of features belonging to one training example is also known as a vector. (A multivariate regression involves multiple features predicting multiple outputs, which will not be covered here)

Multiple regression involves finding multiple weights to minimize the cost function of a training set of data. Each input feature is multiplied by its respective weight to produce the model's prediction. Like in linear regression, the bias term can be thought of as the prediction when all features are zero-valued. When features and weights are both represented as vectors, we take the dot product of the two and add the bias term to calculate the model's prediction.

Vectorization

Vectorization is an efficient technique to perform vector calculations. Instead of using a for loop to calculate the dot product, or manually typing out the element-wise products, which can be tedious, using numpy's dot method requires only one line of code and is computationally more efficient. It is computationally efficient because it uses parallelization (computing multiple calculations simultaneously) to execute the calculations. This parallelism is enabled by the underlying hardware. GPU's and modern CPU's implement Single Instruction, Multiple Data (SIMD) pipelines allowing multiple operations to be executed in parallel.

Vectorization vs sequential calculation

Imagine using a for loop and a cumulative sum to calculate the cost function of a model that has multiple weights and corresponding training inputs. The algorithm must complete and store the results of one calculation before moving on to the next one in the sequence. In other words, it performs calculations sequentially. In contrast, a vectorized algorithm computes each calculation at the same time, then sums the results of the calculations all at once.

In small datasets and models, the performance differences between the two may be negligible. However, in larger datasets and models, the differences can be quite dramatic. This is why it is best practice to use vectorization when possible.

Conventions

Dimension or rank are terms used to describe the number of elements in a vector. Dimension can also be used to describe the number of indexes in an array (the number of elements the size() function returns)

When declaring a dimensional data struct in python, the first parameter of the constructor typically specifies the shape of the struct. The argument can be a scalar or a tuple.

Matrix dimensions are described with mxn tuples, with the elements representing rows and columns respectively.

The reshape method, when used on a vector/array, can be used to create a matrix from an array by specifying the number of rows and columns. if -1 is used for a row/column, it dynamically computes the respective number of rows/columns based on the number of elements and the value provided for the other dimension, and generates a matrix of that shape

Gradient descent for multiple linear regresssion

For multiple regression, the cost function is calculated the same way for each weight, but applied to each weight and its respective input. The gradient descent update for each coefficient becomes

\({\omega}_j := {\omega}_j - \alpha \frac{1}{m} \sum_{i=1}^{m} \left(f_{\vec{\omega},b}(\vec{x}^{(i)}) - y^{(i)}\right)x_j^{(i)}\)

where \(f_{\vec{\omega},b}(\vec{x}^{(i)})\) is the model prediction for training example \(i\), and \(\vec{x}^{(i)}\) is the feature vector for that example. Note that the inner function \(\vec{x}^{(i)}\) and the weights \(\vec{\omega}\) are now vectors. Because the weights \({\omega}_j\) are stored in a vector, all the weights are updated simultaneously in each gradient descent iteration.

Feature Scaling

Feature scaling is a technique that can improve gradient descent performance. Given a feature \(x_1\) with values ranging from \(1-5\) and a feature \(x_2\) with values ranging from \(1-100\). We can say that \(x_1\) has a smaller range of values than \(x_2\). In this example, a model will choose smaller weights for features that have large values, and larger weights for features with relatively small values. It follows that \(w_1\) has a larger range than \(w_2\). When plotting the cost function as a function of \(w_1\) and \(2_2\) on a contour plot, we would see that the algorithm oscillates on the \(w_1\) scale for every small step it takes on the \(w_2\) scale. The contour plot is asymmetric. This oscillation results in a slower convergence time. To speed up the convergence time, we can scale the features appropriately so that they are on similar scales, reducing the amount of oscillation.

Feature scaling desired outcome

Recall that the objective of feature scaling is to improve gradient descent performance by normalizing features to similar ranges and scales. Generally, it is desirable to bound the feature values between -1 and 1. In practice, deviations from this ideal range are acceptable: -3 to 3 and -0.3 to 0.3 are fine. 0 to 3 for \(x_1\) is even okay, even when a separate feature \(x_2\) is in the range of -2 to 0.5. Situations you might want to rescsale: \(x_3\) in the range of -100 to 100, \(x_4\) in the range of -0.001 to 0.001. The ranges are too big and too small. In the case of \(x_5\) ranging from 98.6 to 105, the range is in-family, but the values themselves are too large. So this feature is a prime candidate for rescaling. Feature scaling is almost never harmful, so if it is cheap to do, it should be done.

Feature Scaling Techniques

Assuming the training data values are all nonnegative, a rudimentary technique is to divide each training feature by the maximum value of its feature set (assuming all training features are positive). This bounds each feature between 0 and 1. A more generalizable version of this technique is to rescale each feature by both its minimum and maximum values using \(x_{i_{transformed}} = (x_i - x_{imin})/(x_{imax}-x_{imin})\).

Another technique for centering a feature's values near 0 is known as mean normalization. To perform a mean normalization for a particular feature \(x_i\), find the mean, \(\mu_i\) of the feature and the difference between the maximum and minimum value of that feature. To transform each feature example, subtract the mean and divide the result by the difference: \(x_{i_{transformed}} = (x_i - \mu_i)/(x_{imax}-x_{imin})\).

Z-score normalization: The result of this technique is a feature with a mean of 0 and a standard deviation of 1. For a feature, calculate the mean \(\mu_1\) and standard deviation \(\sigma_1\). Subtract \(\mu_1\) from a feature example and divide the result by \(\sigma_1\): \(x_{i_{transformed}} = (x_i - \mu_i)/\sigma_1\).

When normalizing features, it is important to store the mean and standard deviations. After learning the parameters from the model, we want to apply the model to a dataset it has not yet encountered. The mean and standard deviation are used to normalize the unseen data.

Notably, these techniques do not alter the distribution of the data, only its scale.

Checking gradient descent for convergence

Plot the cost function values against the number of iterations that have occurred. This is called a learning curve. This plot can alert you to a poorly chosen learning rage \(\alpha\) or a bug in the code. The cost function has likely converged when the learning curve has flattened out. The number of iterations needed for convergence varies by the application. Another way to flag for convergence is by using an \(\epsilon\) value, which is the delta of the cost function between two different iterations that we can define to declare convergence. Ng prefers to use a learning curve to observe the behavior as the algorithm converges.

Choosing a learning rate

The learning curve can suggest that the \(\alpha\) is too large. If the cost function is oscillating or steadily increasing, \(\alpha\) may require a reduction. These behaviors could also suggest that there is a bug in the code, for example if the learning rate term is being added to the weight instead of being subtracted. A functional \(\alpha\) results in a steadily decreasing learning curve. A very small \(\alpha\) can be used to debug code - if the learning curve is not steadily decreasing, this suggests an error in the code. If there are no errors, \(\alpha\) can be increased (but not by too much!) to improve convergence performance. Ng uses threefold scaling factors after a successful attempt with \(\alpha\) and adjusts from there.

Exploratory data analysis

Before training a model on the training set, we plot each feature data against the target data to spot any relationships.

Feature engineering

When we have a particular insight about a dataset, we can engineer features by transforming or combining existing ones to improve the prediction accuracy. For example, frontage (width of a plot of land) and length of a housing plot may be engineered into an area feature (frontage x length) that can be added to the training example, which can then be used to predict price.

Polynomial regression (another form of feature engineering)

If the relationship between a feature and the target is nonlinear, polynomial terms can be engineered from the existing feature to provide a better model fit to the data. For example, squaring, cubing, or taking the root of an existing feature and using it as a new feature can help the model provide more accurate predictions. Here, feature scaling is even more important due to the increased scale of the derived features.

When gradient descent is applied to a model with polynomials, it tends to emphasize the terms that fit the data best (increases their weights) and deemphasizes the other terms. Less weight value implies less important/correct feature.

An alternate way of thinking about fitting polynomials to targets is that the best features are actually linear relative to the target.

With feature engineering, complex functions can be modeled.

Scikit-learn models

Scikit-learn has a gradient descent regression model sklearn.linear_model.SGDRegressor

  • Performs best with normalized inputs
  • sklearn.preprocessing.StandardScaler performs z-score normalization, AKA 'standard score'

Code sample using scikit learn below

import numpy as np
import matplotlib.pyplot as plt
from sklearn.linear_model import SGDRegressor
from sklearn.preprocessing import StandardScaler
from lab_utils_multi import  load_house_data
from lab_utils_common import dlc
np.set_printoptions(precision=2)
plt.style.use('./deeplearning.mplstyle')

# load the training set
X_train, y_train = load_house_data()
X_features = ['size(sqft)','bedrooms','floors','age']

# scale/normalize the training data
scaler = StandardScaler()
X_norm = scaler.fit_transform(X_train)
print(f"Peak to Peak range by column in Raw        X:{np.ptp(X_train,axis=0)}")   
print(f"Peak to Peak range by column in Normalized X:{np.ptp(X_norm,axis=0)}")

# Create and fit the regression model
sgdr = SGDRegressor(max_iter=1000)
sgdr.fit(X_norm, y_train)
print(sgdr)
print(f"number of iterations completed: {sgdr.n_iter_}, number of weight updates: {sgdr.t_}")

# View the parameters
b_norm = sgdr.intercept_
w_norm = sgdr.coef_
print(f"model parameters:                   w: {w_norm}, b:{b_norm}")
print( "model parameters from previous lab: w: [110.56 -21.27 -32.71 -37.97], b: 363.16")

# Make predictions
# make a prediction using sgdr.predict()
y_pred_sgd = sgdr.predict(X_norm)
# make a prediction using w,b. 
y_pred = np.dot(X_norm, w_norm) + b_norm  
print(f"prediction using np.dot() and sgdr.predict match: {(y_pred == y_pred_sgd).all()}")

print(f"Prediction on training set:\n{y_pred[:4]}" )
print(f"Target values \n{y_train[:4]}")

# plot predictions and targets vs original features    
fig,ax=plt.subplots(1,4,figsize=(12,3),sharey=True)
for i in range(len(ax)):
    ax[i].scatter(X_train[:,i],y_train, label = 'target')
    ax[i].set_xlabel(X_features[i])
    ax[i].scatter(X_train[:,i],y_pred,color=dlc["dlorange"], label = 'predict')
ax[0].set_ylabel("Price"); ax[0].legend();
fig.suptitle("target versus prediction using z-score normalized model")
plt.show()

Linear Regression Practice Lab Lessons Learned

The problem statement is this: Suppose you are the CEO of a restaurant chain and want to expand to new, more profitable cities. Given that you already have restaurants in many cities and profit/population data from those, can you use your data to predict which cities could be good candidates to give your business higher profits?

  1. Start by loading the population/profit data for all your existing restaurants.
  2. Explore some of the data, and familiarize yourself with some examples. Verify that the data looks as you expect it to. If it doesn't, perhaps the data is in a different range than you were expecting, the units are different, or maybe there is some bad data. Also verify the data's dimensions. It is important the data is fit for model-building.
  3. Build plots to visualize the data!

Linear regression refresher: Building a good linear regression model involves selecting the weights that minimize the cost function. So the cost function is dependent on the weights. Gradient descent improves the weight selection by updating the weights iteratively. It does so by subtracting the product of the learning rate and derivative of the cost function (with respect to the weight) from the previous weight value. When gradient descent can no longer improve the weights, i.e. when there is not a significant difference in cost function between iterations, the model is considered "trained" and can now make predictions on non-training data.

The lab has you code up the cost function and gradient descent. With vectorized code in mind, I found it was easier to write out my thoughts as comments first, then translate them to vectorized code. My cost function ended up being 3 lines, although it could probably be condensed to 1 (at the cost of readability).

def compute_cost(x, y, w, b): 
    """
    Computes the cost function for linear regression.

    Args:
        x (ndarray): Shape (m,) Input to the model (Population of cities) 
        y (ndarray): Shape (m,) Label (Actual profits for the cities)
        w, b (scalar): Parameters of the model

    Returns
        total_cost (float): The cost of using w,b as the parameters for linear regression
               to fit the data points in x and y
    """
    # number of training examples
    m = x.shape[0] 

    # You need to return this variable correctly
    total_cost = 0

    ### START CODE HERE ###
    # x and y are single column vectors
    # model makes a prediction f_wb(x^(i)) based on an input x^(i)
    f_wb = w * x + b # f_wb is a column vector of length m, is the model's prediction for each x
    # cost is the difference between the prediction and true output, squared
    cost_vec = (f_wb - y) ** 2 # vector (length m) of the cost for each training example
    # the cost over all predictions and outputs for the feature set are summed and divided by (2m)
    total_cost = sum(cost_vec) / (2*m)

    ### END CODE HERE ### 

    return total_cost
def compute_gradient(x, y, w, b): 
    """
    Computes the gradient for linear regression 
    Args:
      x (ndarray): Shape (m,) Input to the model (Population of cities) 
      y (ndarray): Shape (m,) Label (Actual profits for the cities)
      w, b (scalar): Parameters of the model  
    Returns
      dj_dw (scalar): The gradient of the cost w.r.t. the parameters w
      dj_db (scalar): The gradient of the cost w.r.t. the parameter b     
     """

    # Number of training examples
    m = x.shape[0]

    # You need to return the following variables correctly
    dj_dw = 0
    dj_db = 0

    ### START CODE HERE ###

    # single variable linear regression depends on gradient descent for each weight: w, b
    # the gradient descent for each weight is calculated using the partial derivative of the cost function with
    # respect to the weight
    # the partial derivative with respect to w is: (f_wb - y) * x
    # the partial derivative with respect to b is: (f_wb - y)
    # This is absolutely true when there is one training example x, and one target y.
    # But when there are multiple training examples, the gradient should be based on all of the training examples. 
    # So we take the average gradient across all training examples: sum(w_gradients)/m and sum(b_gradients)/m

    f_wb = w * x + b # f_wb is a column vector of length m, is the model's prediction for each x

    dj_dw = (1 / m) * sum((f_wb - y) * x)
    dj_db = (1 / m) * sum((f_wb - y))


    ### END CODE HERE ### 

    return dj_dw, dj_db

After cwriting compute_gradient, the function can now be used iteratively in a gradient descent algorithm. The algorithm should iteratively improve the weights (the cost function should decrease each time). The algorithm is a loop of: calculate gradient, update weight, measure cost. The end condition can be set as a number of iterations or a mimimum cost function delta between successive iterations.

Classification

Home stretch of the course! After a few days of refreshing regression basics, I am excited to get to classification. The course so far has been refreshing. I've been able to explore the topics in more depth than I did in the ML4T class.

Some classification applications: determining if email is spam, determining if a transaction is fraudulent, determining if a tumor is malignant. A classification model makes a categorization based on whether the probability of an input being in a category exceeds the decision boundary.

Classification predicts discrete categories, while regression predicts real numbers. Here's a question: given a training data set of single-column real-valued inputs mapped to binary outputs, what happens if I use a linear regression model to deterimine categories? Assume that I have found a linear regression model that fits the data (it probably won't fit all that well, because the training data is not linear. You might see where this is going). To use it for classification, I would need to assign a decision boundary. The decision boundary would be affixed to the model where \(f(x)\) is equal to 0.5 (the midpoint between binary outputs 0 and 1). The x-value of this decision boundary is the point that differentiates inputs that get a positive classification. What happens to this decision boundary when outliers are added to the training set? Well, the linear regression would change as a result of the outliers, so the x-value of the decision boundary would also change. This isn't ideal behavior - we don't want a different input to change the way the model makes a classification. An example that is positive, no matter to what degree it is, shouldn't change what prediction the model makes. Since linear regression is affected by these outliers, it's not ideal for classification. So we'll want to use a different function.

Logistic regression

Despite having "regression" in the name, logistic regression is used for classification! According to Ng, it is one of the most widely used classification algorithms in the world. Logistic regression uses a function called a sigmoid. A sigmoid function \(f(z) = 1 / (1 + e^{-z})\) is used for classification because it transforms all inputs to an output existing between 0 and 1.The output can also be understood as the probability that an input should be classified as 1/positive. When z is 0, the sigmoid function is valued at 0.5. 0.5 is often chosen as a decision boundary - the threshold that determines which category an input belongs to. In other words, 50% probability is the threshold separating a negative and positive classification.

Decision Boundaries

When the input of the sigmoid function \(z\) is substituted with a function such as \(-3 + x_0+x_1\) or \(x_0^2 + x_1 -1\), the function determines the shape of the decision boundary.

Cost function for logistic regression

In linear regression, the MSE cost function was used because its convexity allowed the algorithm to converge to a minimum. In logistic regression, the same cost function doesn't work well because the logistic function is nonlinear. When MSE is applied to logistic regression, the cost function exhibits several local minima, which is not ideal for the gradient descent algorithm. Instead of MSE, we'll use a different cost function.

Important vocabulary distinction: loss is a measure of the difference between a prediction and its target, while cost is the sum of losses from an entire training set.

The loss of a sigmoid function is calculated using two separate curves. One is for the case when the true value is positive and the other for when the true value is negative. The behavior of the cost function is as such: when the prediction is close to the true value, the loss is near zero. But when the prediction is close to the opposite of the true value, the loss rapidly approaches infinity. Combined, the two curves make a convex shape, which is an ideal form for gradient descent. The loss function is described as such: \(loss(f_{\mathbf{w},b}(\mathbf{x}^{(i)}), y^{(i)}) = (-y^{(i)} \log\left(f_{\mathbf{w},b}\left( \mathbf{x}^{(i)} \right) \right) - \left( 1 - y^{(i)}\right) \log \left( 1 - f_{\mathbf{w},b}\left( \mathbf{x}^{(i)} \right) \right)\). Notice that the loss function is comprised of two main terms. When the true prediction is positive, or 1, one term is nullified. The other term is nullified when the true prediction is negative, or 0.

This particular loss function is derived using a statistical principle called maximum likelihood estimation, which is an idea from statistics about how to efficiently find ideal parameters from different models.

To derive the cost function, simply add up the losses from each training example and divide by the number of training examples.

Batch gradient descent for logistic regression

Just like in regression, the weights are updated by subtracting the a product of the learning rate and the gradient of the cost function from the weight's current value. \(\begin{align*} &\text{repeat until convergence:} \; \lbrace \\ & \; \; \;w_j = w_j - \alpha \frac{\partial J(\mathbf{w},b)}{\partial w_j} \tag{1} \; & \text{for j := 0..n-1} \\ & \; \; \; \; \;b = b - \alpha \frac{\partial J(\mathbf{w},b)}{\partial b} \\ &\rbrace \end{align*}\)

How is the gradient of the cost function calculated in this case? It turns out, the cost function gradient takes a similar form to the one in linear regression. That is, \(\begin{align*} \frac{\partial J(\mathbf{w},b)}{\partial w_j} &= \frac{1}{m} \sum\limits_{i = 0}^{m-1} (f_{\mathbf{w},b}(\mathbf{x}^{(i)}) - y^{(i)})x_{j}^{(i)} \tag{2} \\ \frac{\partial J(\mathbf{w},b)}{\partial b} &= \frac{1}{m} \sum\limits_{i = 0}^{m-1} (f_{\mathbf{w},b}(\mathbf{x}^{(i)}) - y^{(i)}) \tag{3} \end{align*}\) The only difference now is that \((f_{\mathbf{w},b}(\mathbf{x}^{(i)})\) is the sigmoid function, rather than a linear function. The derivation is omitted from this lecture, and can be an exercise for the reader.

def compute_gradient_logistic(X, y, w, b): 
    """
    Computes the gradient for logistic regression 

    Args:
      X (ndarray (m,n): Data, m examples with n features
      y (ndarray (m,)): target values
      w (ndarray (n,)): model parameters  
      b (scalar)      : model parameter
    Returns
      dj_dw (ndarray (n,)): The gradient of the cost w.r.t. the parameters w. 
      dj_db (scalar)      : The gradient of the cost w.r.t. the parameter b. 
    """
    m,n = X.shape
    dj_dw = np.zeros((n,))                           #(n,)
    dj_db = 0.

    for i in range(m):
        f_wb_i = sigmoid(np.dot(X[i],w) + b)          #(n,)(n,)=scalar, prediction for a training example
        err_i  = f_wb_i  - y[i]                       #scalar, error for a full training example
        for j in range(n):
            dj_dw[j] = dj_dw[j] + err_i * X[i,j]      #scalar, for each weight accumulate product of full training example error and X[i, j] (example for that weight). the gradient of each weight depends on these two quantities
        dj_db = dj_db + err_i                         # gradient of bias depends only on the error
    dj_dw = dj_dw/m                                   #(n,)
    dj_db = dj_db/m                                   #scalar

    return dj_db, dj_dw 

In gradient descent, the weights are updated by a quantity that depends on the learning rate \(\alpha\) and the gradient. The gradient is recalculated for each iteration, and depends on the model's error. For non-bias parameters, the weights depend on the product of the error and training examples. For the bias parameter, the gradient is dependent on the error only. The gradient can be understood as a measure of how far away the weights are from their optimal (minimal error) value. When the gradient is large, the model is far from converging. When the gradient is small or near-zero, the weights are near convergence, or have converged.

Logistic Regression with Scikit-Learn
import numpy as np

# dataset
X = np.array([[0.5, 1.5], [1,1], [1.5, 0.5], [3, 0.5], [2, 2], [1, 2.5]])
y = np.array([0, 0, 0, 1, 1, 1])

from sklearn.linear_model import LogisticRegression

# fit the model
lr_model = LogisticRegression()
lr_model.fit(X, y)

# make predictions
y_pred = lr_model.predict(X)

print("Prediction on training set:", y_pred)

# calculate accuracy
print("Accuracy on training set:", lr_model.score(X, y))

Overfitting

When a model underfits the data, it can also be said to have high bias.

A model that "generalizes" well is one that fits the training set pretty well (but not perfectly!) and accurately predicts unseen examples.

A model that "overfits" fits the training set extremely well (perfectly or near-perfectly) but does not accurately predict unseen samples. These models are said to have high variance. They are highly sensitive to small changes in the training data.

3 techniques to address overfitting

The goal of these techniques is to reduce the variance, which will help the model generalize better.

Increasing the training set size will prevent the model from overfitting a few pieces of data. This may not always be possible in situations where data is scarce.

Using a subset of existing features will also reduce overfitting. The subset to focus on would be those that are most predictive of the output. This technique is called feature selection. The drawback of this method is that some discarded features could be uesful in predicting the output. There do exist algorithms that automatically select the most appropriate features for prediction tasks.

Regularization is a technique that diminishes (but does not totally eliminate) the impact that certain features have on the prediction. Instead of eliminating a particular feature by setting all of its parameters to zero, regularization tunes the examples such that the weights for those features end up being very small. This allows for higher-order models to be used without encountering high variance. In practice, the w weights are typically regularized, as opposed to regularizing b. Regularizing b often has little effect on reducing variance. Regularization is also used in neural networks!

Overfitting Lab
  • Polynomials of excessively high degree tend to overfit
  • conversely, polynomials of excessively low degree tend to underfit
  • extreme examples can increase overfitting (assuming they are outliers)
  • nominal examples can reduce overfitting
  • fitting a line to smaller datasets can be done without pure gradient descent (implementation method not mentioned, however)
Modifying the cost function to accomodate regularization

Simply add the weights that you want to minimize to the cost function, and multiply them by relatively large coefficients. The exact quantity doesn't matter as much, but by putting large coefficients in front of these weights, the cost function penalizes these weights heavily when they are large. Assuming that the weights being penalized correspond to higher-order terms, regularization effectively makes the model behave as a lower-order model, thus reducing overfitting.

To generalize this technique, such as in instances where there are many features and we don't know which ones to regularize, we can simply regularize all of them. This is implemented by adding a regularization term to the cost function that looks like \(\frac{\lambda}{2m} \sum\limits_{j = 1}^{n} (w_j^2)\), where \(m\) is the number of training examples, \(n\) is the number of weights, and \(\lambda\) is a hyperparameter that controls the strength of the regularization penalty. When \(\lambda\) is large, the cost function penalizes the weights so much that the only weight left over is the constant bias term, \(b\). When \(\lambda\) is very small, the regularization term is effectively nullified, and high variance can exist in the model. The \(\frac{\lambda}{2m}\) scaling factor makes it likelier for lambda to work with larger datasets (larger \(m\)) as it did for smaller ones.

gradient descent with regularization

The only difference between the gradients for non-regularized and regularized models is that the gradient for \(\mathbf{w}\) includes a new term: the partial derivative of the regularization term with respect to \(w_j\), which turns out to be \(\frac{\lambda}{m}w_j\). As stated previously, \(b\) is not typically regularized, so in most circumstances there is no need to add a regularization term to its gradient in the regularized case, making it identical to the non-regularized gradient.

Final lab: building a logistic regression model from scratch
  1. Visualize the shape of the data by viewing dimensions of data, peeking at values, plotting features vs. output

    import numpy as np
    import matplotlib.pyplot as plt
    from utils import *
    import copy
    import math
    
    %matplotlib inline
    # load dataset
    X_train, y_train = load_data("data/ex2data1.txt")
    
    print("First five elements in X_train are:\n", X_train[:5])
    print("Type of X_train:",type(X_train))
    
    print("First five elements in y_train are:\n", y_train[:5])
    print("Type of y_train:",type(y_train))
    
    print ('The shape of X_train is: ' + str(X_train.shape))
    print ('The shape of y_train is: ' + str(y_train.shape))
    print ('We have m = %d training examples' % (len(y_train)))
    
    # Plot examples
    plot_data(X_train, y_train[:], pos_label="Admitted", neg_label="Not admitted")
    
    # Set the y-axis label
    plt.ylabel('Exam 2 score') 
    # Set the x-axis label
    plt.xlabel('Exam 1 score') 
    plt.legend(loc="upper right")
    plt.show()
    

  2. Implement the sigmoid function. The input to the sigmoid function can be a scalar or a vector. To handle vectors, I used the np.power method to calculate the exponential in the denominator.

    def sigmoid(z):
        """
        Compute the sigmoid of z
    
        Args:
            z (scalar or ndarray): A scalar or numpy array of any size.
    
        Returns:
            g (scalar or ndarray): sigmoid(z), with the same shape as z if z is a numpy array.
    
        """
    
        ### START CODE HERE ### 
        g = 1 / (1 + np.power(np.e,-z))
        ### END SOLUTION ###  
    
        return g
    

  3. Implement the cost function. I broke this down into three lines of code, each being a component of the cost: linear model output, \(g(z)\), loss, and cost. The linear model output is obtaind by calculating the dot product of the training examples and the weights and adding the bias term. \(g(z)\), otherwise known as the sigmoid output, is simply the result of the linear model output when it is fed into the sigmoid function that I wrote in the previous step. To calculate the loss, I used the binary cross-entropy loss (log loss). Notably, the natural log function is typically used, rather than the base 10 log function. Functionally speaking, gradient descent will work with either implementation, but natural log is preferred because it simplifies the gradient calculation. Using base 10 log introduces a scaling factor that clutters the derivation.

    def compute_cost(X, y, w, b, *argv):
        """
        Computes the cost over all examples
        Args:
          X : (ndarray Shape (m,n)) data, m examples by n features
          y : (ndarray Shape (m,))  target value 
          w : (ndarray Shape (n,))  values of parameters of the model      
          b : (scalar)              value of bias parameter of the model
          *argv : unused, for compatibility with regularized version below
        Returns:
          total_cost : (scalar) cost 
        """
    
        m, n = X.shape
    
        ### START CODE HERE ###
    
        # total cost is the average loss calculation for each training example
        # the loss function input is the output of the sigmoid function
        # the output of the sigmoid function depends on the output of the linear model
        linear_model = np.dot(X, w) + b
    
        # let g be the sigmoid output
        g = sigmoid(linear_model)
    
        # the loss for each example in g depends on the difference between g and the actual value in y
        loss = (-y * np.log(g)) - ((1 - y) * np.log(1 - g))
    
        # total cost is the sum of all losses divided by the number of training examples
        total_cost = sum(loss) / m
    
        ### END CODE HERE ### 
    
        return total_cost
    

  4. Implement the gradient for logistic regression The skeleton code for this section uses a double nested for loopm, but I opted to vectorize when possible. Like the cost function calculation, the gradient depends on the difference between the sigmoid output of the linear model (prediction delta) and the true label. dj_db was calculable using vectorization. Each dj_dw value (one for each weight) was obtained by calculating the average value of [the product of each prediction delta and its input feature value], for all feature examples. This was the only part of the code that requried a for loop.

    def compute_gradient(X, y, w, b, *argv): 
        """
        Computes the gradient for logistic regression 
    
        Args:
          X : (ndarray Shape (m,n)) data, m examples by n features
          y : (ndarray Shape (m,))  target value 
          w : (ndarray Shape (n,))  values of parameters of the model      
          b : (scalar)              value of bias parameter of the model
          *argv : unused, for compatibility with regularized version below
        Returns
          dj_dw : (ndarray Shape (n,)) The gradient of the cost w.r.t. the parameters w. 
          dj_db : (scalar)             The gradient of the cost w.r.t. the parameter b. 
        """
        m, n = X.shape
        dj_dw = np.zeros(w.shape)
        dj_db = 0.
    
    #     ### START CODE HERE ### 
    #     for i in range(m):
    #         z_wb = None
    #         for j in range(n): 
    #             z_wb += None
    #         z_wb += None
    #         f_wb = None
    
    #         dj_db_i = None
    #         dj_db += None
    
    #         for j in range(n):
    #             dj_dw[j] = None
    
    #     dj_dw = None
    #     dj_db = None
        ### END CODE HERE ###
    
        # not sure why for loop is being used here. trying vectorization instead
        linear_model = np.dot(X, w) + b
        g = sigmoid(linear_model)
        dj_db = (1 / m) * sum(g - y)
        for j in range(n):
            dj_dw[j] = (1 / m) * sum((g - y) * (X[:,j]))
    
        return dj_db, dj_dw
    

  5. Using the weights and predictions from gradient descent, plot the results The weights that gradient descent converges on are the parameters for the decision boundary. Gradient descent code, which was provided, is included here.

def gradient_descent(X, y, w_in, b_in, cost_function, gradient_function, alpha, num_iters, lambda_): 
    """
    Performs batch gradient descent to learn theta. Updates theta by taking 
    num_iters gradient steps with learning rate alpha

    Args:
      X :    (ndarray Shape (m, n) data, m examples by n features
      y :    (ndarray Shape (m,))  target value 
      w_in : (ndarray Shape (n,))  Initial values of parameters of the model
      b_in : (scalar)              Initial value of parameter of the model
      cost_function :              function to compute cost
      gradient_function :          function to compute gradient
      alpha : (float)              Learning rate
      num_iters : (int)            number of iterations to run gradient descent
      lambda_ : (scalar, float)    regularization constant

    Returns:
      w : (ndarray Shape (n,)) Updated values of parameters of the model after
          running gradient descent
      b : (scalar)                Updated value of parameter of the model after
          running gradient descent
    """

    # number of training examples
    m = len(X)

    # An array to store cost J and w's at each iteration primarily for graphing later
    J_history = []
    w_history = []

    for i in range(num_iters):

        # Calculate the gradient and update the parameters
        dj_db, dj_dw = gradient_function(X, y, w_in, b_in, lambda_)   

        # Update Parameters using w, b, alpha and gradient
        w_in = w_in - alpha * dj_dw               
        b_in = b_in - alpha * dj_db              

        # Save cost J at each iteration
        if i<100000:      # prevent resource exhaustion 
            cost =  cost_function(X, y, w_in, b_in, lambda_)
            J_history.append(cost)

        # Print cost every at intervals 10 times or as many iterations if < 10
        if i% math.ceil(num_iters/10) == 0 or i == (num_iters-1):
            w_history.append(w_in)
            print(f"Iteration {i:4}: Cost {float(J_history[-1]):8.2f}   ")

    return w_in, b_in, J_history, w_history #return w and J,w history for graphing
np.random.seed(1)
initial_w = 0.01 * (np.random.rand(2) - 0.5)
initial_b = -8

# Some gradient descent settings
iterations = 10000
alpha = 0.001

w,b, J_history,_ = gradient_descent(X_train ,y_train, initial_w, initial_b, 
                                   compute_cost, compute_gradient, alpha, iterations, 0)

plot_decision_boundary(w, b, X_train, y_train)
# Set the y-axis label
plt.ylabel('Exam 2 score') 
# Set the x-axis label
plt.xlabel('Exam 1 score') 
plt.legend(loc="upper right")
plt.show()
  1. Make a prediction baesd on the learned weights
def predict(X, w, b): 
    """
    Predict whether the label is 0 or 1 using learned logistic
    regression parameters w

    Args:
      X : (ndarray Shape (m,n)) data, m examples by n features
      w : (ndarray Shape (n,))  values of parameters of the model      
      b : (scalar)              value of bias parameter of the model

    Returns:
      p : (ndarray (m,)) The predictions for X using a threshold at 0.5
    """
    # number of training examples
    m, n = X.shape   
    p = np.zeros(m)

    ### START CODE HERE ### 
    # Loop over each example
    # feed each example through f(g(z)). in other words, put it through the linear model, 
    # then put the output of the linear model to the sigmoid function for the prediction
#     for i in range(m):   
#         z_wb = 0
#         # Loop over each feature
#         for j in range(n): 
#             # Add the corresponding term to z_wb
#             z_wb += X[i][j] * w[j]

#         # Add bias term 
#         z_wb += b

#         # Calculate the prediction for this example
#         f_wb = sigmoid(z_wb)

#         # Apply the threshold
#         p[i] = (f_wb >= 0.5)

    z_wb = np.dot(X, w) + b
    f_wb = sigmoid(z_wb)
    p = (f_wb >= 0.5)

    ### END CODE HERE ### 
    return p

# Test your predict code
np.random.seed(1)
tmp_w = np.random.randn(2)
tmp_b = 0.3    
tmp_X = np.random.randn(4, 2) - 0.5

tmp_p = predict(tmp_X, tmp_w, tmp_b)
print(f'Output of predict: shape {tmp_p.shape}, value {tmp_p}')

# UNIT TESTS        
predict_test(predict)
  1. Tying it all together with regularized logistic regression Given a dataset containing test result data for a microchip, and a determination (pass, failed) of the microchip after QA analysis, we want to predict whether a microchip with test results will pass or fail.

Plotting the data reveals that the potential decision boundary would be ill-served with a linear model.

So to increase our chances of finding a better model, we construct new features from each data point.

Given two features, \(x_1\) and \(x_2\), we map the features into all polynomial terms of these features of a 6th order polynomial.

\[\mathrm{map\_feature}(x) = \left[\begin{array}{c} x_1\\ x_2\\ x_1^2\\ x_1 x_2\\ x_2^2\\ x_1^3\\ \vdots\\ x_1 x_2^5\\ x_2^6\end{array}\right]\]

The function that does this was provided in the lab. The feature mapping function increased the number of features from 2 to 27.

The intent with this feature mapping is to improve the model's ability to fit the data. Without regularization, the model is susceptible to overfitting/high variance.

To implement regularization, an extra term is added to the cost function for the weights in \(\vec{w}\). \(b\) doesn't need a regularized term, since it purportedly has little effect on the outcome.

def compute_cost_reg(X, y, w, b, lambda_ = 1):
    """
    Computes the cost over all examples
    Args:
      X : (ndarray Shape (m,n)) data, m examples by n features
      y : (ndarray Shape (m,))  target value 
      w : (ndarray Shape (n,))  values of parameters of the model      
      b : (scalar)              value of bias parameter of the model
      lambda_ : (scalar, float) Controls amount of regularization
    Returns:
      total_cost : (scalar)     cost 
    """

    m, n = X.shape

    # Calls the compute_cost function that you implemented above
    cost_without_reg = compute_cost(X, y, w, b) 

    # You need to calculate this value
    reg_cost = 0.

    ### START CODE HERE ###

    reg_cost = (lambda_ / (2 * m)) * sum(w ** 2)

    ### END CODE HERE ### 

    # Add the regularization cost to get the total cost
    total_cost = cost_without_reg + reg_cost

    return total_cost

For the gradient, the update is similar:

def compute_gradient_reg(X, y, w, b, lambda_ = 1): 
    """
    Computes the gradient for logistic regression with regularization

    Args:
      X : (ndarray Shape (m,n)) data, m examples by n features
      y : (ndarray Shape (m,))  target value 
      w : (ndarray Shape (n,))  values of parameters of the model      
      b : (scalar)              value of bias parameter of the model
      lambda_ : (scalar,float)  regularization constant
    Returns
      dj_db : (scalar)             The gradient of the cost w.r.t. the parameter b. 
      dj_dw : (ndarray Shape (n,)) The gradient of the cost w.r.t. the parameters w. 

    """
    m, n = X.shape

    dj_db, dj_dw = compute_gradient(X, y, w, b)

    ### START CODE HERE ###     

    dj_dw += (lambda_ / m) * w

    ### END CODE HERE ###         

    return dj_db, dj_dw

It is after this step that gradient descent can be used to learn the weights. Once the weights have been learned, they can be used to plot the decision boundary and predict the inputs.

And that concludes the topics covered in this course! I had a lot of fun learning regression and classification basics and I am excited to continue on to Advanced Learning Algorithms.

Areas for Further Exploration

I realized there were a few areas for me to dive deeper into while learning from the lectures. Some fundamentals could be refreshed/learned. Some derivation details were left out, as well as fundamental statistical ideas, such as maximum likelihood estimation.

Databases

For my first summer term in OMSCS, I completed the Database Systems Concepts and Design course! I was curious about backend data management after taking Machine Learning for Trading in the spring. This class definitely delivered on that front and provided me with a solid foundation in databases and database management systems. In this post, I'll describe how I designed an application database from scratch. I undertook this task in 3 phases: analysis, design, and implementation. Along the way, I learned how to think about building a consistent database application from first principles, how to work with teammates from different countries and time zones, built my first ever web application, and gained experience designing the full stack.

The Customer

PowerShare is a nonprofit organization that wishes to accumulate data regarding households in the United States, specifically around alternative power sources and other household properties.

The Requirements

The requirements document contained descriptions of data that PowerShare wanted to collect from users, as well as mockups of the web application. Household, appliance, and power generation data was collected from the user and displayed in reports. The data collected was “open” in the sense that any user of the application was able to submit their data. Conversely, any user could browse the selected set of reports available on the PowerShare website.

In industry, this document is generated with the help of various stakeholders: product managers, architects, developers, QA, UX/UI designers, and DevOps, among other roles. Luckily for us, the requirements document abstracted away countless meetings and change requests, freeing up valuable summertime hours. :)

Analysis

I used several tools to capture the results of our analysis: an information flow diagram, extended entity relationship (EER) diagram, attribute tables, task decompositions, and abstract code. It's quite a mouthful, but the main point of these tools is to help organize the planning before any code has been written. The information flow diagram is the highest-level diagram and maps each application functionality with the type(s) of database interaction. The EER diagram captures all entities associated with the database and describes their attributes and relationships with each other. Attribute tables summarize the data types and business constraints for attributes associated with each entity. Finally, the task decomposition associates each spoke of the information flow diagram with a piece of abstract code. The abstract code is a language-agnostic representation of the application's functionality. It captures the core logic of teh application code, so its intent can be implemented in any language or framework.

The analyis is useful for distilling the functionality of the web application from a database perspective. It is also easier to further refine requirements with stakeholders by using a common language, such as these tools. The implementation phase adds a level of complexity that is best tackled after analysis has been conducted. Most importantly about the three-phase process is that it is quite iterative. I found myself amending previous diagrams/tables as we went deeper towards the implementation.

Collected data could be ingested in several formats such as decimals, integers, and strings. Some data had additional constraints, such as zip codes being limited to five digits or latitude/longitude values being limited to their respective measurements in degrees. Validating the input data before it was added to the database was important, as incompatible data could seriously affect the quality and accuracy of the reports. This analysis process is rigorous, and is best suited towards applications that depend on database management systems. These types of applications tend to manage large volumes of data, provide access to multiple users concurrently, enforce constraints

Design

With most of the high-level thinking completed in the analysis phase, I refined these ideas in the design phase. The abstract code was updated with syntactical SQL queries. I replaced the attribute tables with entity relationship maps, which is just a fancy way of describing a diagram of schemas connected by their foreign keys.

The most significant deliverable in the design phase was a .sql script containing definitions of schemas and constraints in the DBMS. Each table had its own CREATE statement. It also contained DROP statements preceding the CREATE statements, so it could be used to completely wipe an existing database. For our project, I chose PostgreSQL due to its popularity, which would invariably enable us to use the ample documentation, forum posts, and Youtube tutorials to our advantage. Going forward, I think this is a great way to go about building a personal project from scratch. I'd recommend using more niche/bespoke solutions when the problem calls for it and when there is quality developer support. This could come in the form of thorough documentation or having access to the developers of the solution.

Implementation

Now, my favorite part. This was where the rubber hit the road. I had never built a web application before, so I was curious to see how the process would unfold. The teaching staff had suggested some popular stacks, such as LAMP or WAMP. We decided that a Linux-Flask-Python-PostgreSQL (LFPP) would allow us to build out the core functionality while reducing uneeded complexity. The app would be demo'ed by one of us at the final presentation, so a beefier framework was not necessary.

Some important context that I considered at the onset was that each developer would be contributing to the application from their own development environment. Between the four of us, we used Linux, Mac, and Windows operating systems. So configuration management was important. I also considered the idea of extending functionality in the future. It's certainly easier to do that when less time is spent fiddling around with software packages. To this end, I used a Poetry package manager, although a simple pip package manager could have been used as well. To bundle up the entire application (including Postgres), I could have used a Docker container, but this also would have added complexity that wasn't necessary. The application used basic Postgres functionality, so pretty much any Postgres version that was available for download as of July 2026 would have been fine.

For version control, we used git and a shared github repo. The tried and true combination.

With configuration out of the way, I

On blogging

I kept a blog when I was younger. I approached it as a highly polished portfolio of my thoughts. Posts were infrequent and daunting to write. I wrote for others, not myself. Years later, I realized that nourishing this craft through regular practice was more important to me than publishing a 'finished' product every time.

Why write on a personal website? Why not use another service, like Substack?

Many people seem to document their projects/lives using YouTube, Instagram, Substack, etc. However, these companies own their platforms and thus exert influence on the means of creation. They essentially behave as content incubators. I currently have no plans to make writing a career, and I'm not writing for a broad audience. I want my creativity to flourish without the pressure to commercialize, and I want to keep it exclusive, like a walled garden. I believe I can achieve this by creating and hosting a static website on Github Pages. If I ever want to release my works to a broader audience, I can publish them on a platform.

Why write on digital?

The digital world is always at my fingertips. I can access my work from anywhere, and so can the people I share with.

Why writing and not filming?

Writing can be parsed/skimmed easily and doesn't require high activation energy: I simply fire up a Codespaces instance, create a file, and push it to the Github repo. I don't have to think about how I look or sound. Writing puts the ideas at center stage. I chose the mkdocs website as a template for my blog because it makes writing even easier. I need only write in markdown - the plugin automatically converts it to HTML/CSS. I can also go back in time and easily edit my posts. If I'm away from my computer and have recorded ideas in my notes app, I can easily copy and paste them into markdown on my Mac. For these reasons, I think writing digitally is the perfect medium for experimentation. In the future, I may explore voice dictation to reduce friction and save myself some time. I also enjoy hearing my own voice.

Who am I, the writer?

A learner and a sharer.

Who am I writing for?

Primarily future me. I would like to look back at all the progress I've made.

What kind of writing am I posting here?

As this site is always a work in progress (much like myself!), some pieces are in their nascent stages and others are closer to being fully developed. This is a place where I document my experiments. I will call it the Strava for Intellectual Pursuits. Similarly to how my athletic pursuits have shifted over the years, I can quickly try things and move on when it's time.

Housekeeping

Housekeeping

After being away from the digital sharing space for quite some time, I have decided to return!

What have I been up to these past few years?

Well, to put it simply, I've been living and developing as a human being!

Where have I been?

After growing up in Phoenix and graduating college in Somerville, MA, I lived in various cities in the Greater Boston Area. I also moved across the country twice to live in the Bay Area, which is where I currently am. I am extremely privileged to have visited several countries, which include, in no particular order: Canada, Denmark, Sweden, Italy, England, France, Mexico, The Netherlands, Kingdom of Saudi Arabia, Japan, Republic of Korea, and Vietnam. I traveled to some of these countries for work, and managed to find time for play in all of them. More on play in a minute. I seem to enjoy adventuring in large cities. In Amsterdam, I walked an entire day around the city to hunt for the best pie. In Hanoi, I discovered some amazing street food and restaurants by moped, and even took it on a countryside road trip. In Seoul, I ran along the Cheonggyecheon stream and the Han River - a great way to get a long run in and see the sights. I have so many stories to share, which I may include in future posts!

What have I done?

Extracurricularly, I've mostly dabbled in the world of sports. I took up fishing for a few weeks when COVID initially broke out as a way to spend quality time social distancing. I managed to overcome my disgust of hooking worms and even caught a juvenile largemouth bass. I ultimately discovered that I desired a little more stimulation, so I stored my rod and lures and headed over to the local rock climbing gyms, where I spent a good many hours enjoying the company of people and thinking about colorful plastic rocks. As I accumulated friends and tendon strength, I eventually began projecting V7's until I caught the running bug and decided to devote my time away from work to getting faster. As my upper body muscular definition faded, my lower body muscles increasingly became adept at running longer distances. Running is fun, but not in the same way climbing is. Running is fun because

What's next?

More time devoted to pursuing my interests and passions, and continued growth and learning!